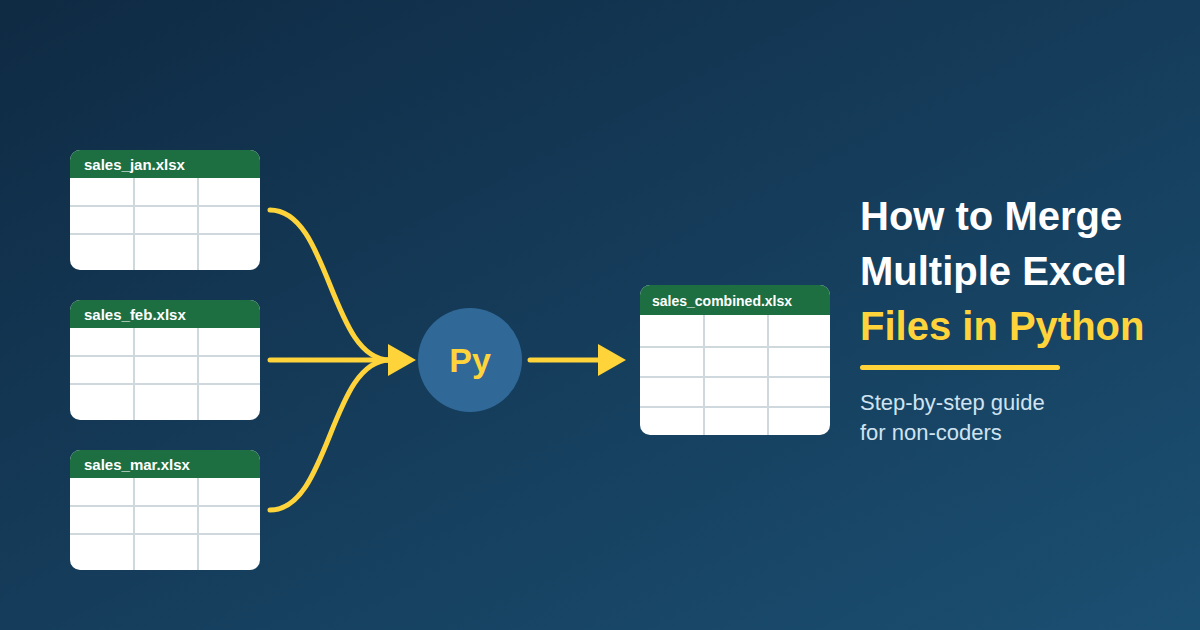
It’s the 28th of the month. You have sales_jan.xlsx, sales_feb.xlsx and sales_mar.xlsx open in three windows. You are copying rows from one file, pasting them into a master workbook, and hoping you didn’t skip a block. Next month you’ll do it again.
This guide shows you how to merge multiple Excel files with Python in about 15 lines of code. You don’t need coding experience. If you can install a program and edit a file path, you can follow along. Once the script works, a monthly job that takes an hour takes a few seconds.
What you’ll need
- Python 3.10 or newer. Pandas drops support for old Python versions regularly, so check the minimum for your pandas version [VERIFY].
- pandas, which reads and combines tables.
- openpyxl, which lets pandas read and write .xlsx files.
Open a terminal (Command Prompt on Windows) and run:
pip install pandas openpyxl
If pip isn’t recognized, try python -m pip install pandas openpyxl.
The example data
Every file has the same three columns:
| Date | Product | Amount |
| 2026-01-03 | Keyboard | 45.00 |
| 2026-01-05 | Monitor | 189.99 |
Put the files in a folder called monthly_sales. Keep the final merged file outside that folder. I’ll explain why in the mistakes section.
Step 1: Find all the Excel files
The script needs a list of files to merge. We use pathlib to collect every file in the folder that starts with sales_ and ends in .xlsx. This beats typing each filename by hand, because next month’s file gets picked up automatically.
from pathlib import Path
folder = Path(“monthly_sales”) # folder that holds your files
files = sorted(folder.glob(“sales_*.xlsx”)) # sorted keeps the order predictable
print(files) # check that every file you expect is listed
Run this much first. If the list is empty, the folder path is wrong. Fix that before going further.
Step 2: Read each file into a table
Pandas calls a table a DataFrame. We read each file into one and add a column recording which file the row came from. When a number looks wrong later, that column tells you where to look.
import pandas as pd Python Programming Guide for Beginners
frames = [] # an empty list to collect tables
for file in files:
df = pd.read_excel(file, engine=”openpyxl”) # read the first sheet
df[“Source File”] = file.name # remember where each row came from
frames.append(df)
By default read_excel reads only the first sheet. If your data lives on another sheet, add sheet_name=”Sales” (use your real sheet name).
Step 3: Stack the tables together
Now we join the tables into one, one below the other. ignore_index=True renumbers the rows from 0. Without it, every file keeps its own numbering and you get duplicate row numbers.
combined = pd.concat(frames, ignore_index=True)
Pandas matches columns by name, not position. If Amount is the third column in one file and the second in another, it still lines up correctly. This is one reason the approach is safer than copy-paste.
Step 4: Clean the dates
Dates are the most common source of trouble. Excel may store some as real dates and others as text. Converting the whole column to one type means sorting and filtering work properly later.
combined[“Date”] = pd.to_datetime(combined[“Date”]) # one consistent date type
combined = combined.sort_values(“Date”) # oldest first
Step 5: Save the merged file
combined.to_excel(“sales_combined.xlsx”, index=False) # index=False skips the 0,1,2… column
Open sales_combined.xlsx and check the row count. It should equal the sum of the rows in your source files (minus one header row per file).
The complete script
Copy this into a file called merge_excel.py, adjust the folder name, and run it with python merge_excel.py.
from pathlib import Path
import pandas as pd
# — Settings you can change —
FOLDER = Path(“monthly_sales”) # folder with your monthly files
PATTERN = “sales_*.xlsx” # which files to include
OUTPUT = Path(“sales_combined.xlsx”) # saved OUTSIDE the folder above
# 1. Find the files
files = sorted(FOLDER.glob(PATTERN))
if not files:
raise SystemExit(f”No files matching {PATTERN} found in {FOLDER}”)
# 2. Read each file and tag it with its filename
frames = []
for file in files:
df = pd.read_excel(file, engine=”openpyxl”)
df[“Source File”] = file.name
frames.append(df)
print(f”Read {len(df)} rows from {file.name}”)
# 3. Stack all tables into one
combined = pd.concat(frames, ignore_index=True)
# 4. Make dates consistent and sort
combined[“Date”] = pd.to_datetime(combined[“Date”])
combined = combined.sort_values(“Date”)
# 5. Save the result
combined.to_excel(OUTPUT, index=False)
print(f”Saved {len(combined)} rows to {OUTPUT}”)
A mistake almost every beginner makes
Saving the merged file into the same folder as the monthly files. If it’s named sales_combined.xlsx, it matches the sales_*.xlsx pattern. Next month the script merges it with the new files, and every old row appears twice. Your totals double, and nobody notices until a manager asks why.
Keep the output in a different folder, or give it a name the pattern won’t match.
Common errors and fixes
ModuleNotFoundError: No module named ‘pandas’
Pandas isn’t installed for the Python you’re running. Run pip install pandas openpyxl. If it still fails, you may have several Python versions. Use python -m pip install pandas openpyxl so the install matches the interpreter.
ImportError: Missing optional dependency ‘openpyxl’
Pandas can’t read .xlsx without it. Run pip install openpyxl.
FileNotFoundError: [Errno 2] No such file or directory
The path is wrong, or you’re running the script from a different folder than you think. Use a full path such as Path(r”C:\Users\you\Documents\monthly_sales”). The r before the quotes stops Windows backslashes from causing trouble.
PermissionError: [Errno 13] Permission denied: ‘sales_combined.xlsx’
The output file is open in Excel, and Excel locks it. Close it and run the script again.
KeyError: ‘Date’
One file has a different header, such as date or Date with a trailing space, or its table doesn’t start in row 1. Open the file that was being read when the error appeared and check the header. If the header sits lower, use pd.read_excel(file, header=2) (counting from 0).
ValueError: Excel file format cannot be determined, you must specify an engine manually.
The file is probably an old .xls, or a CSV that was renamed to .xlsx. For real .xls files, run pip install xlrd and read them with engine=”xlrd” [VERIFY: current pandas guidance on .xls]. Error wording can differ slightly between pandas versions.
When this approach is a bad idea
Pandas reads values, not formatting. Colors, merged cells, formulas, charts and conditional formatting are lost in the merged file. If your source files are formatted reports you need to preserve, this script won’t do.
Excel also tops out at 1,048,576 rows per sheet. If the combined data could pass that, save to CSV instead (combined.to_csv(…)) or use a database.
And if each file has a different layout, you’ll need to clean each one before merging. Stacking mismatched tables gives you a messy file, just faster.
Bonus tip: one sheet per month, plus a combined sheet
Sometimes you want the merged data and the originals separated in one workbook. This writes both:
with pd.ExcelWriter(“sales_report.xlsx”, engine=”openpyxl”) as writer:
combined.to_excel(writer, sheet_name=”All Sales”, index=False)
for df in frames:
name = df[“Source File”].iloc[0].replace(“.xlsx”, “”) # e.g. sales_jan
df.to_excel(writer, sheet_name=name[:31], index=False) # Excel limits names to 31 characters
FAQ
Can I merge Excel files with different column names?
Yes, but rename the columns first so they match. For example: df = df.rename(columns={“Sale Amount”: “Amount”}). Otherwise pandas creates separate columns and leaves blanks where data is missing.
Will this work on a Mac?
Yes. Pandas and openpyxl work the same on Windows, Mac and Linux. Only the way you write file paths changes slightly.
Can I merge only certain sheets or columns?
Yes. Use sheet_name=”Sales” to pick a sheet and usecols=[“Date”, “Product”, “Amount”] in read_excel to keep only those columns.